Diffusion models for images and video, measured in ComfyUI on our dual Radeon RX 7900 XTX workstation and our RTX 3080 Ti + RTX 3080 workstation. The workflows and raw results are published on GitHub.Image and video generation times from our AMD and NVIDIA workstations.
// image & video · amd
AMD Image and Video Generation
Diffusion models in ComfyUI on our AMD workstation. Since November 7, MiniMax H3 INT8 text to video runs across both cards with tensor parallelism over direct GPU-to-GPU transfers; the other workflows keep the denoiser on one card and the text encoder and VAE on the other.Image and video models in ComfyUI, split across both cards.
One complete request each, from submitting the job to the saved output, as recorded by our test runner on November 7, 2026, in the final card layout (rows marked Nov 5 run: the earlier November 5 run). ComfyUI 0.44 on ROCm 7.2, both cards in use; results vary with the model, settings and hardware. MiniMax H3 Image: November 15, 2026, on ComfyUI 0.45.4, with its files already cached in RAM.
Samples under each model were generated on the same workstation with the same workflows, during our November 5, 2026 benchmark runs.
Qwen-Image 2.1 BF16
Model / precision
Task
Output
Steps
Time
Qwen-Image 2.1 BF16Text to image · 512×512
Text to image
512×512
40
90.3 s
Qwen-Image 2.1 BF16Image edit · 640×416
Image edit
640×416
40
25.94 sNov 5 run
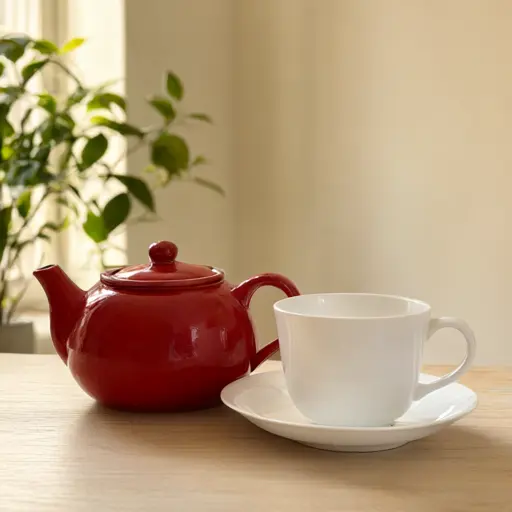
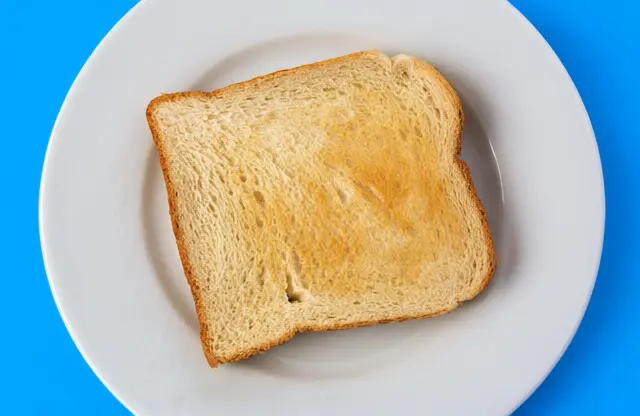
Qwen-Image 2.1 · Text to image, 512×512A red ceramic teapot with a white cup and saucer on a wooden table.Qwen-Image 2.1 · Image edit, 640×416A slice of plain toast on a white plate, against a blue background.
FLUX 3 Image Klein BF16
Model / precision
Task
Output
Steps
Time
FLUX 3 Image Klein BF16Text to image · 1024×1024
Text to image
1024×1024
16
96.5 s
FLUX 3 Image Klein BF16Image edit · 1248×832
Image edit
1248×832
16
42.1 s
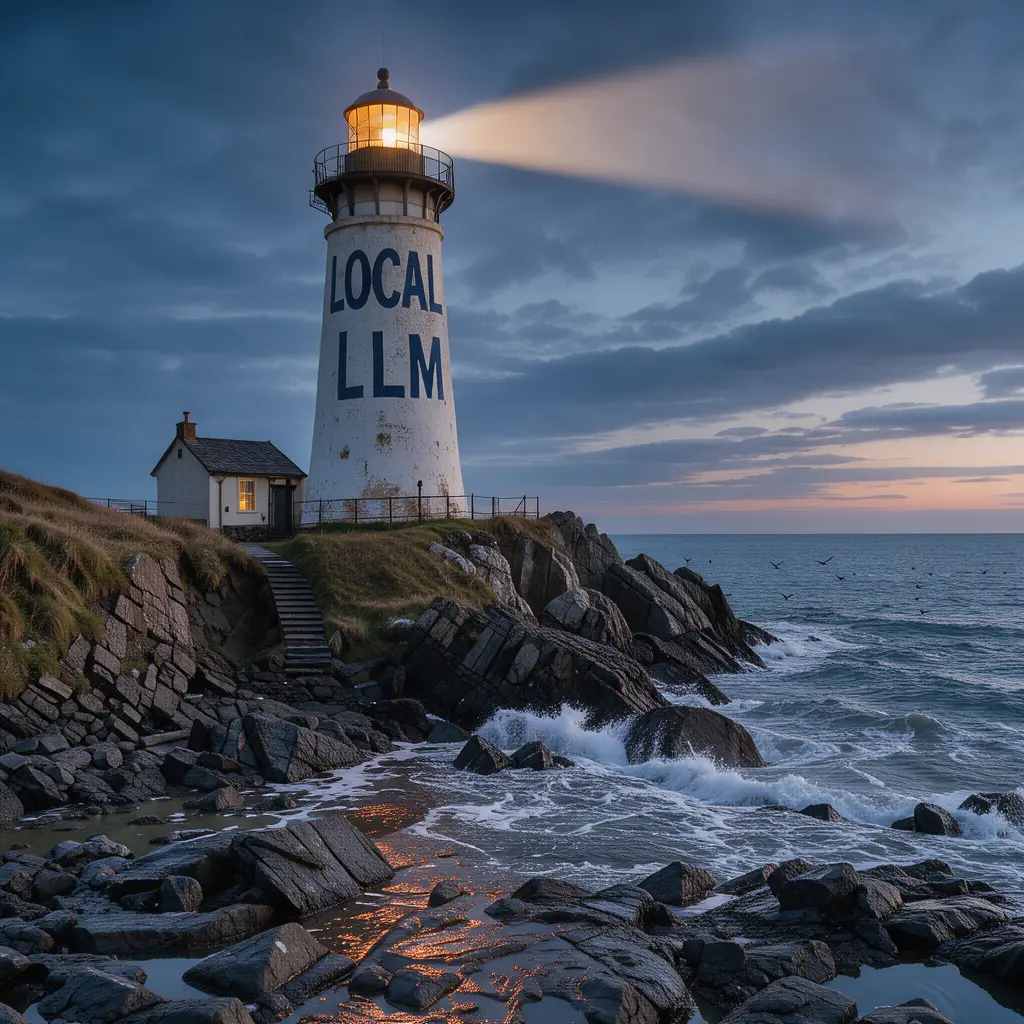
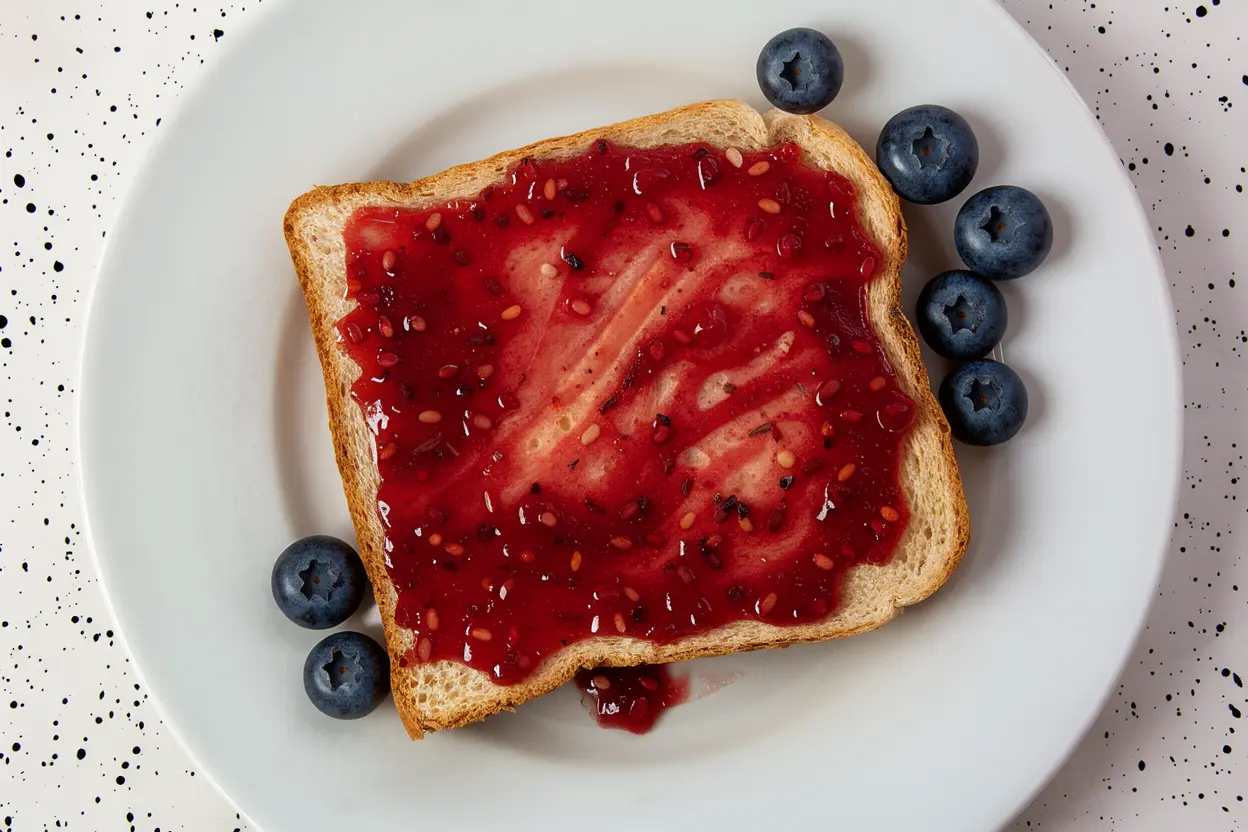
FLUX 3 Image Klein · Text to image, 1024×1024Prompt: “a lighthouse on a rocky coast at dusk, with the words LOCAL LLM painted on its side”FLUX 3 Image Klein · Image edit, 1248×832Edit of a photo of plain toast: “spread strawberry jam on the toast and add a few fresh blueberries on the plate”
MiniMax H3 Image INT8
Model / precision
Task
Output
Steps
Time
MiniMax H3 Image INT8Text to image · 2048×2048
Text to image
2048×2048
6
36.3 s
MiniMax H3 Image INT8Text to image · 4096×4096
Text to image
4096×4096
6
126.3 s
MiniMax H3 Image INT8Image edit · 2048×2048
Image edit
2048×2048
6
64.9 s
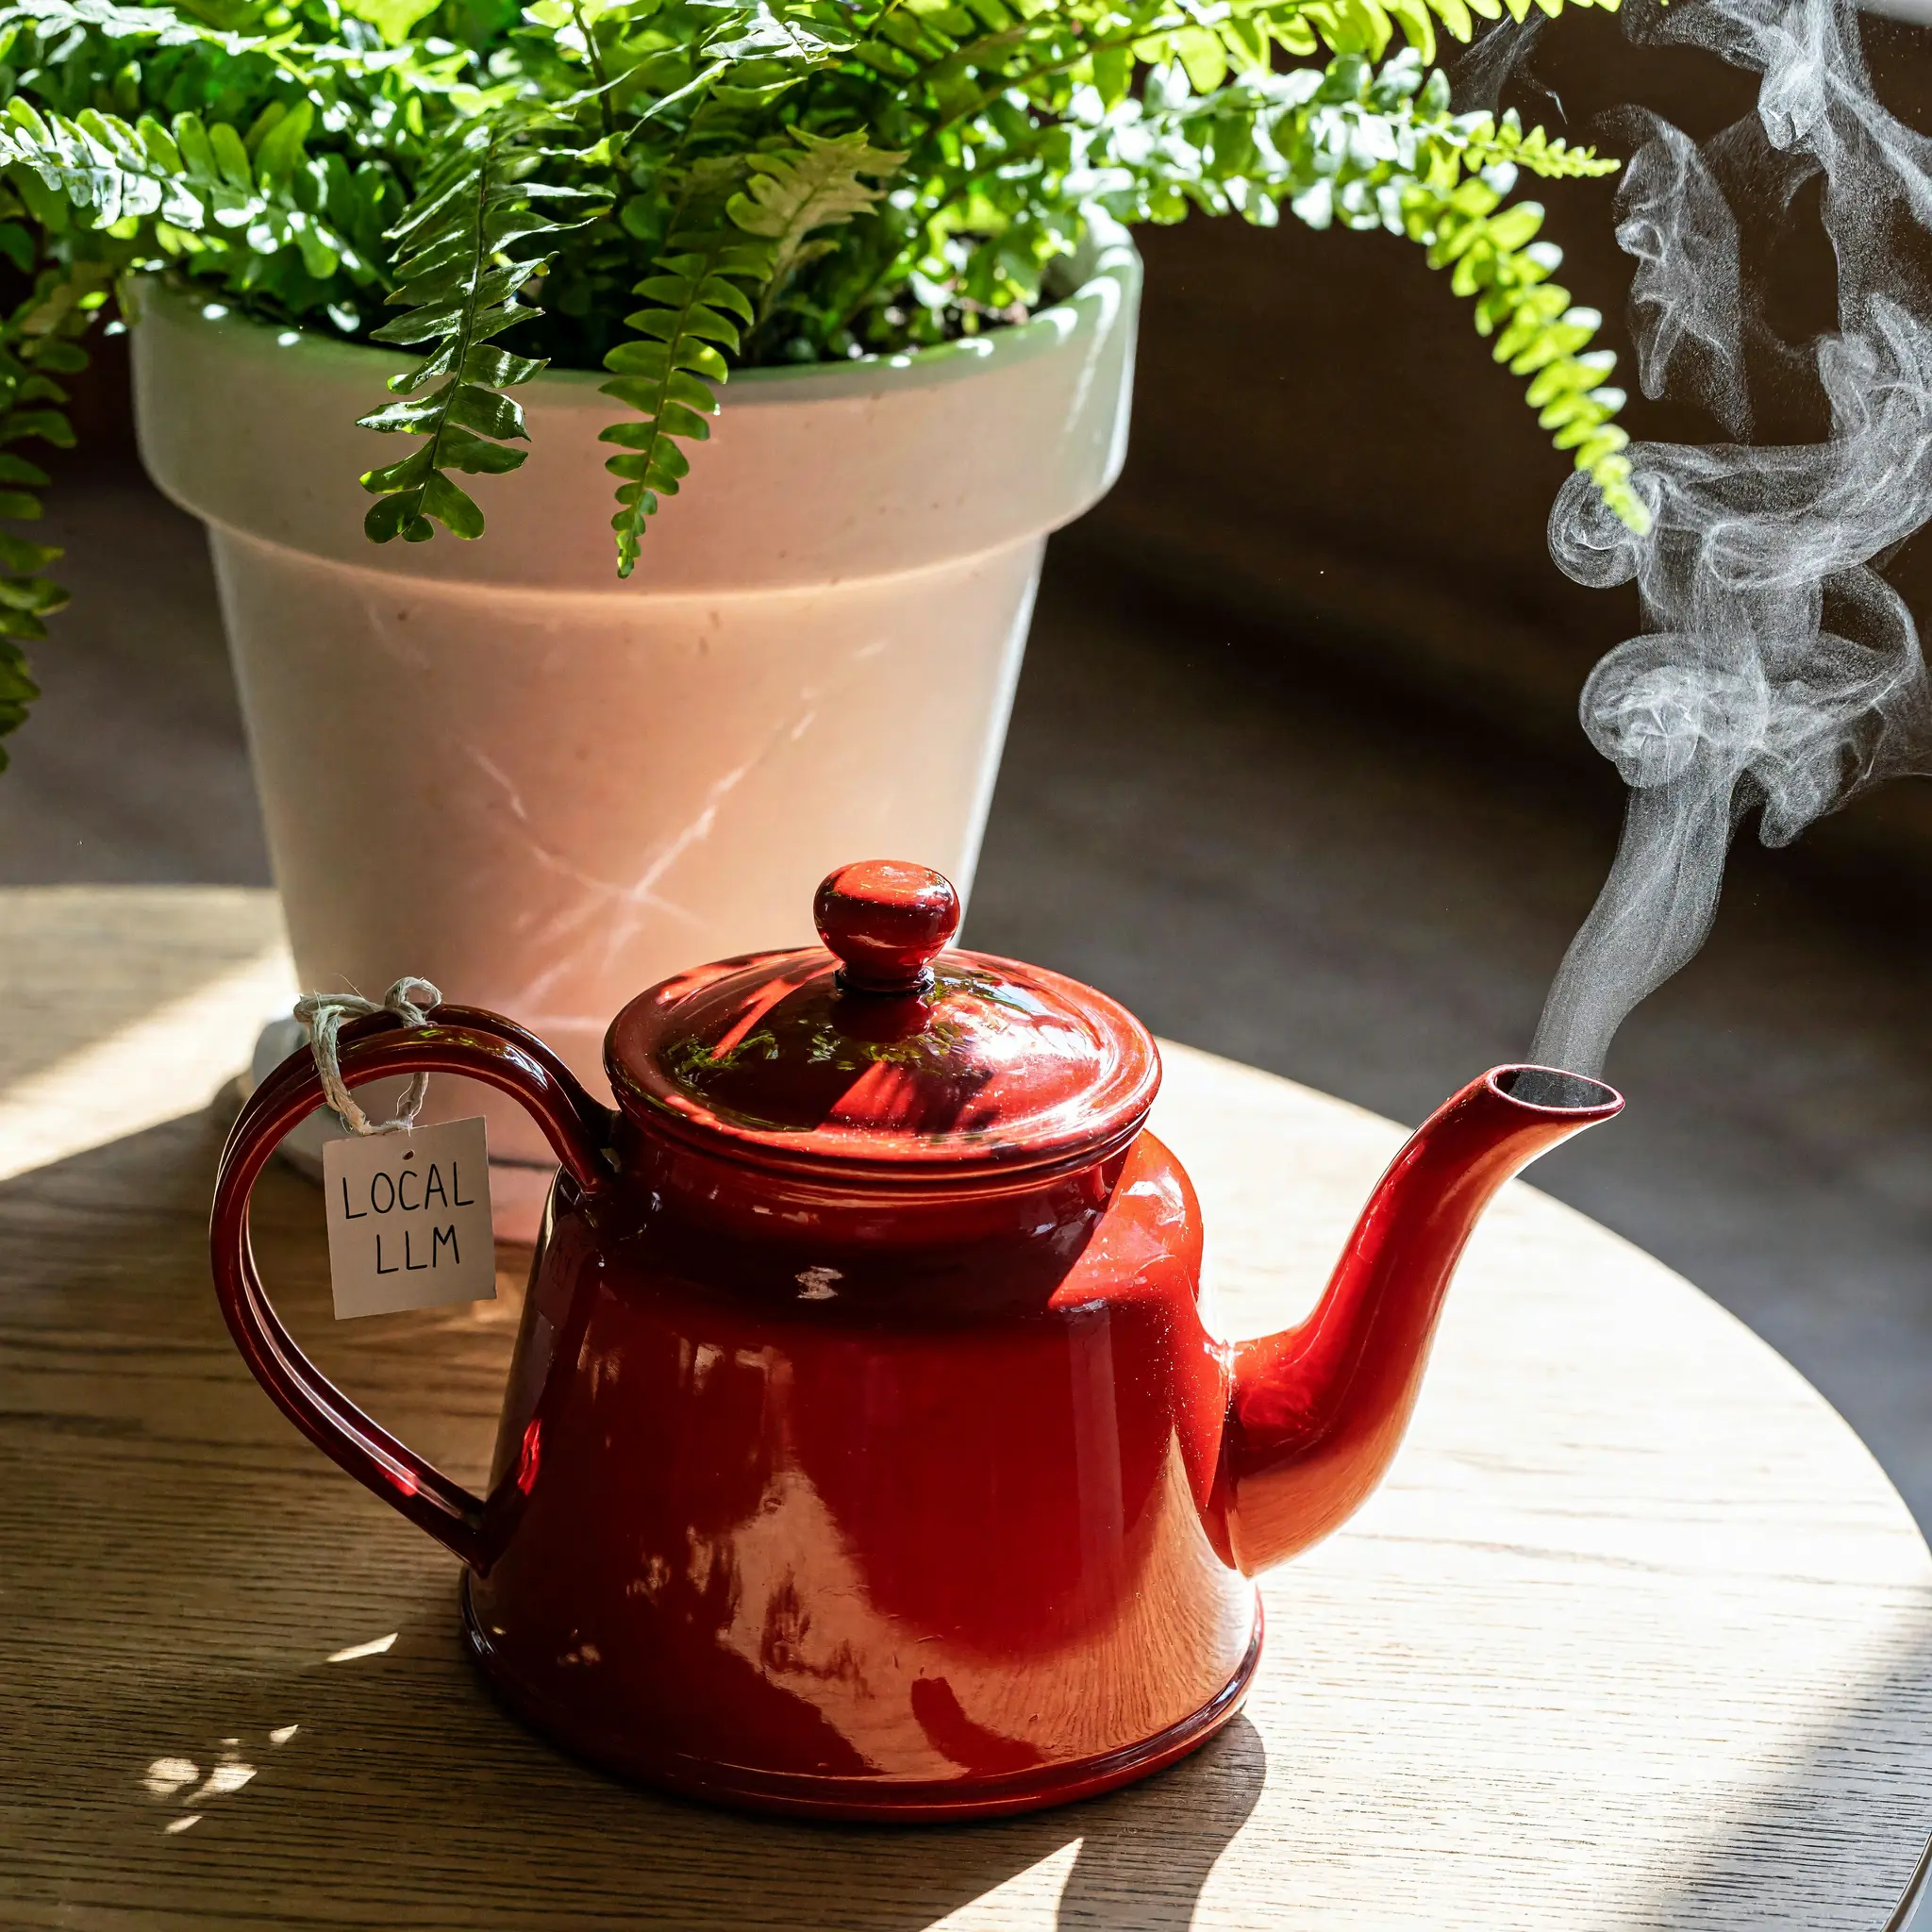
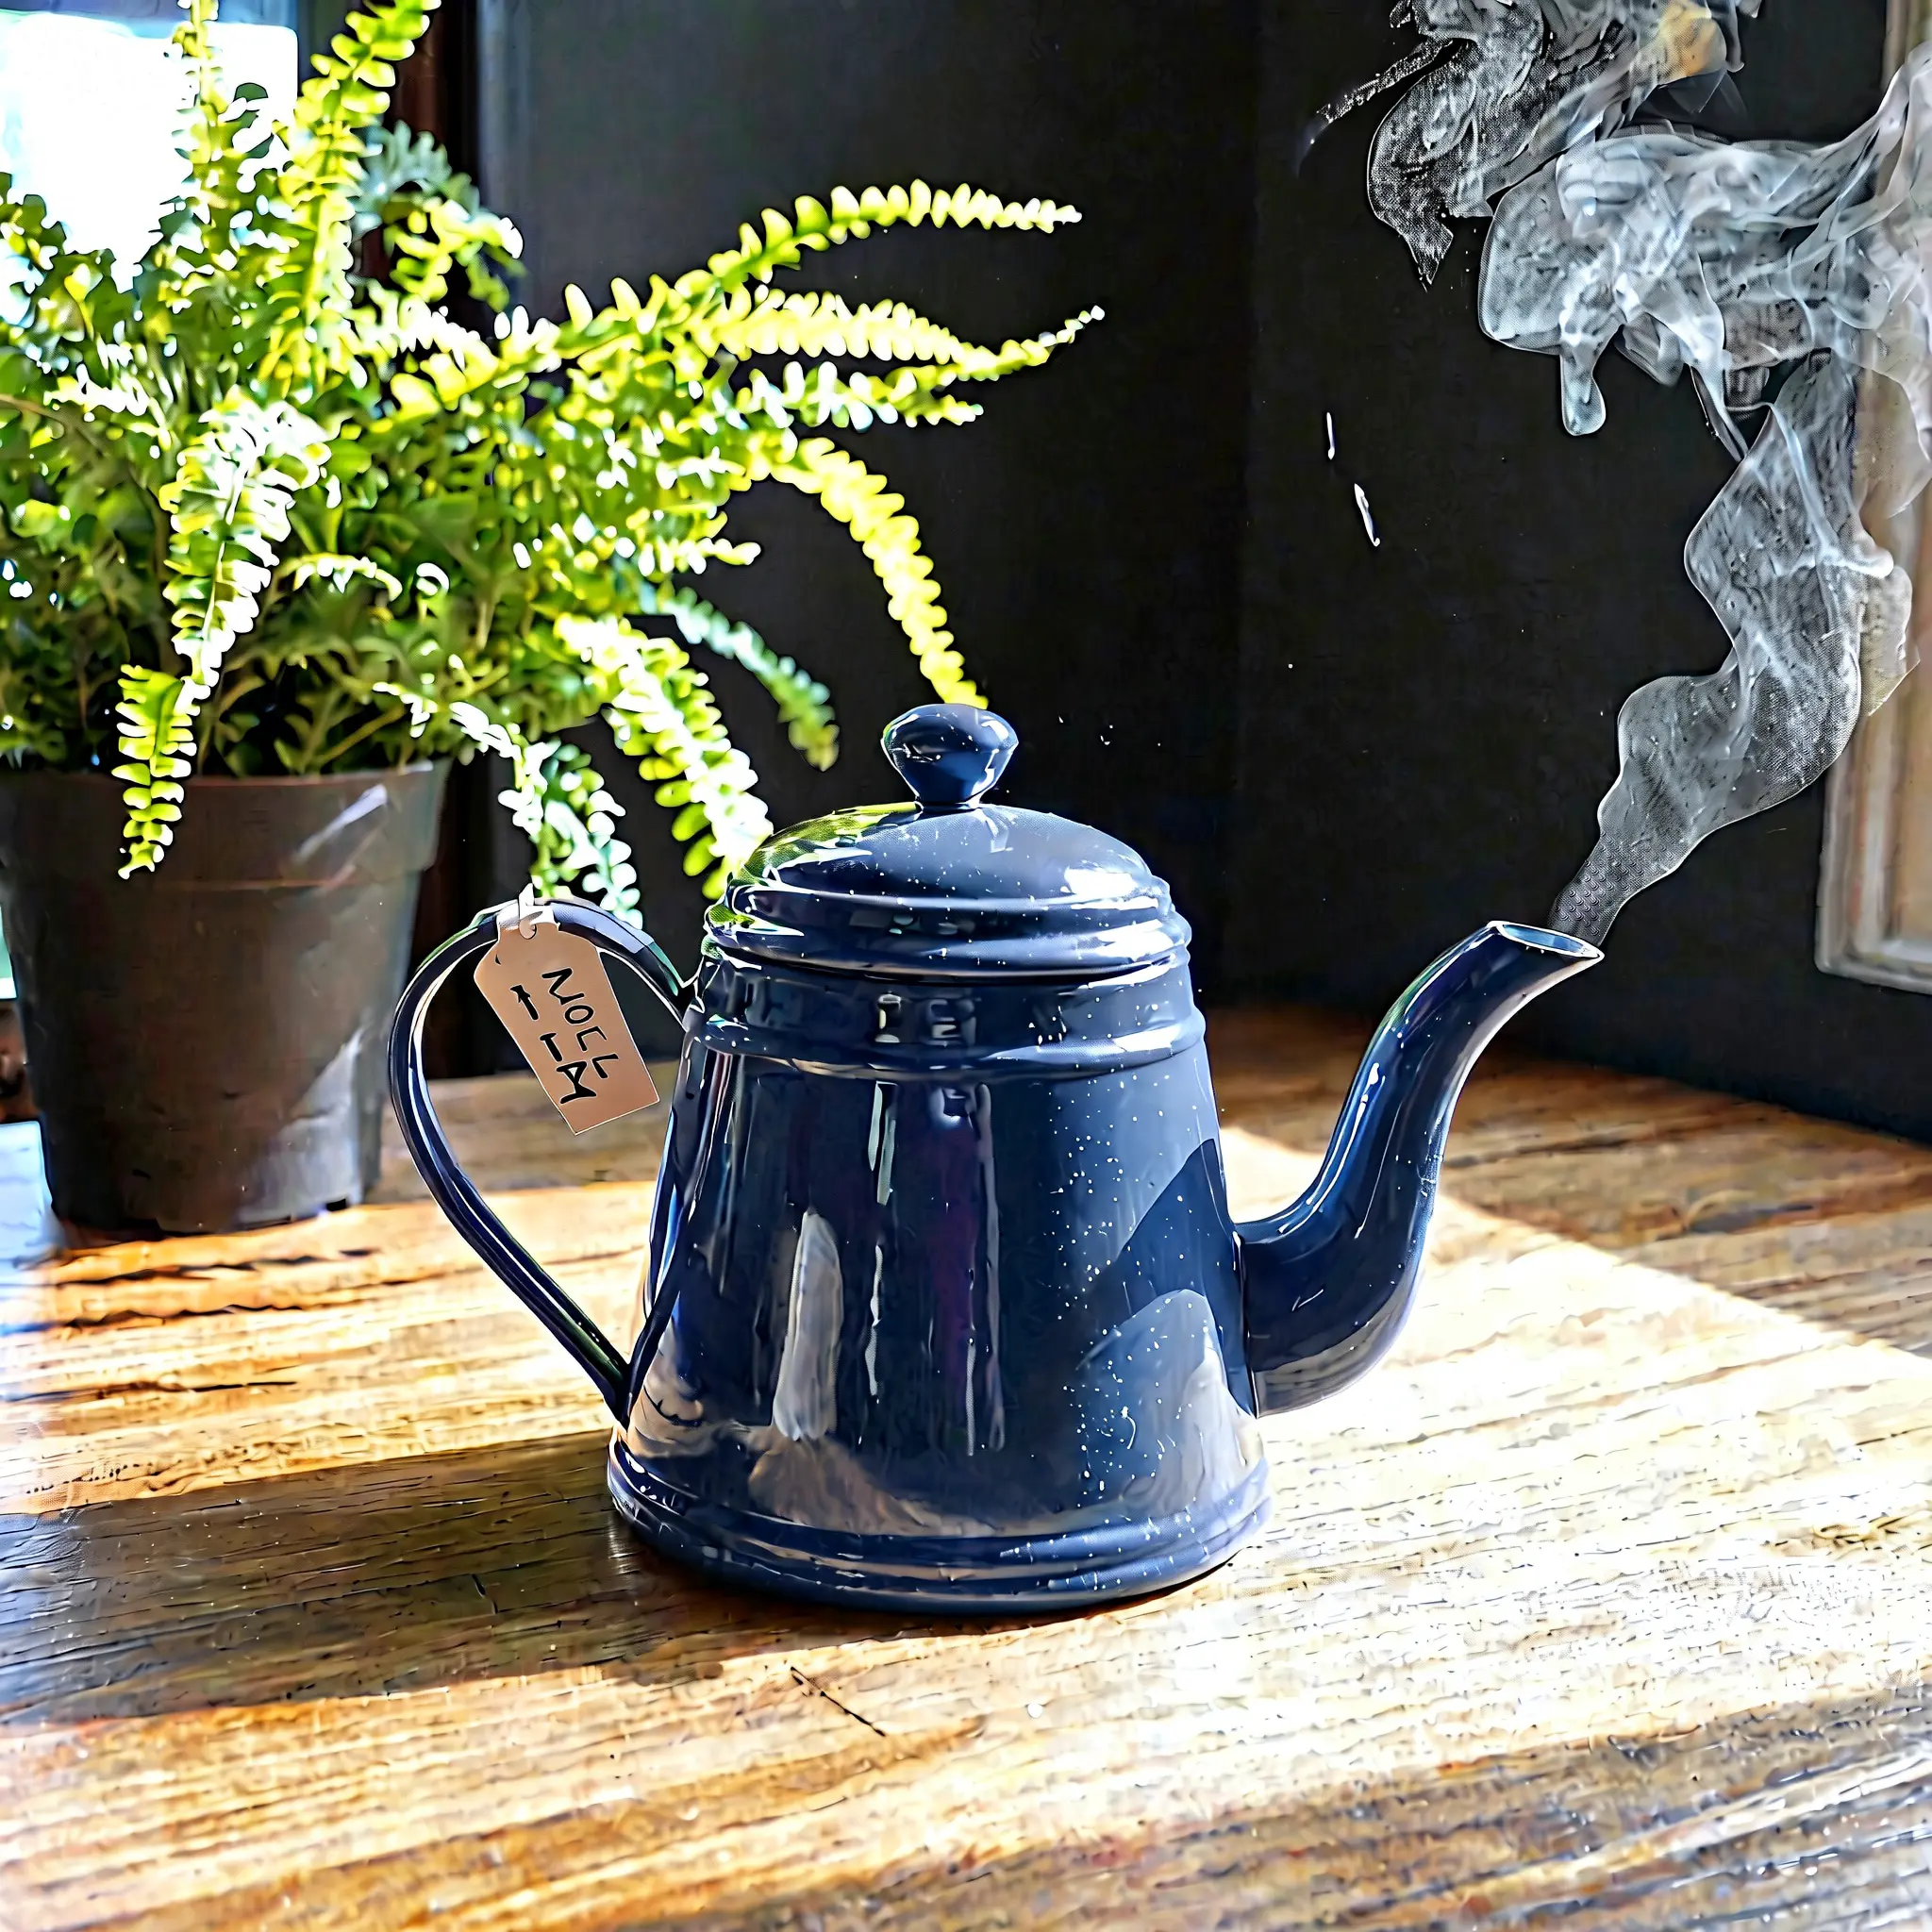
MiniMax H3 Image INT8 · Text to image, 4096×4096 (shown at 2048)Prompt: “A red enamel teapot on a sunlit wooden table beside a potted fern, steam rising from its spout, with a small paper tag on the handle that reads "LOCAL LLM". Full-color indoor photograph.”MiniMax H3 Image INT8 · Image edit, 2048×2048Edit of the 2048×2048 teapot image: “Make the teapot cobalt blue instead of red and replace the fern with a small lemon tree. Keep the table, the light, the steam and the paper tag unchanged.” The teapot turned blue; the fern was not replaced.
MiniMax H3 INT8
Model / precision
Task
Output
Steps
Time
MiniMax H3 INT8Video with audio · 608×352, 39 frames
Video with audio
608×352, 39 frames
20
56.4 smodel already loaded
MiniMax H3 INT8Video with audio · 960×544, 39 frames
Video with audio
960×544, 39 frames
20
132.3 s
MiniMax H3 INT8 · Text to video with audio, 608×352, 1.6 sA red ceramic teapot on a wooden table, with steam rising in warm sunlight. Press play with sound on to hear the audio track.
MiniMax H3 native 32B
Model / precision
Task
Output
Steps
Time
MiniMax H3 native 32BVideo with audio · 608×352, 39 frames
Video with audio
608×352, 39 frames
20
114.3 s
MiniMax H3 native 32BImage to video with audio · 608×352, 39 frames
Image to video with audio
608×352, 39 frames
20
175.5 s
MiniMax H3 native 32B · Image to video with audio, 608×352, 1.6 sAnimated from a photo of plain toast on a plate. Press play with sound on to hear the audio track.
Image and video models in ComfyUI on our NVIDIA workstation, with the denoiser on the RTX 3080 Ti and the text encoder and VAE on the RTX 3080, and no weights offloaded to system memory. LTX 2.3 is too large for one card, so its denoiser is split across both.Image and video models in ComfyUI, split across both cards.
Time from submitting the job to the saved image or video, in a fresh rerun of every model on November 5, 2026. Image rows have the model already loaded (the second image of a pair, with a new seed). Video rows are one clip each and include loading the model and encoding the prompt; starting the worker beforehand is not included. ComfyUI on CUDA, both cards in use; results vary with the model, settings and hardware. MiniMax H3 Image: November 15, 2026, a 3-bit GGUF build with its text encoder kept in system RAM; times are with the model loaded.
Samples under each model were generated on the same workstation during the November 4 and 5, 2026 benchmark runs.
Qwen-Image 2.1 Turbo INT8
Model / precision
Task
Output
Steps
Time
Qwen-Image 2.1 Turbo INT8Text to image · 1024×1024
Text to image
1024×1024
8
4.05 s
Qwen-Image 2.1 Turbo INT8Text to image · 2048×2048
Text to image
2048×2048
8
26.29 s
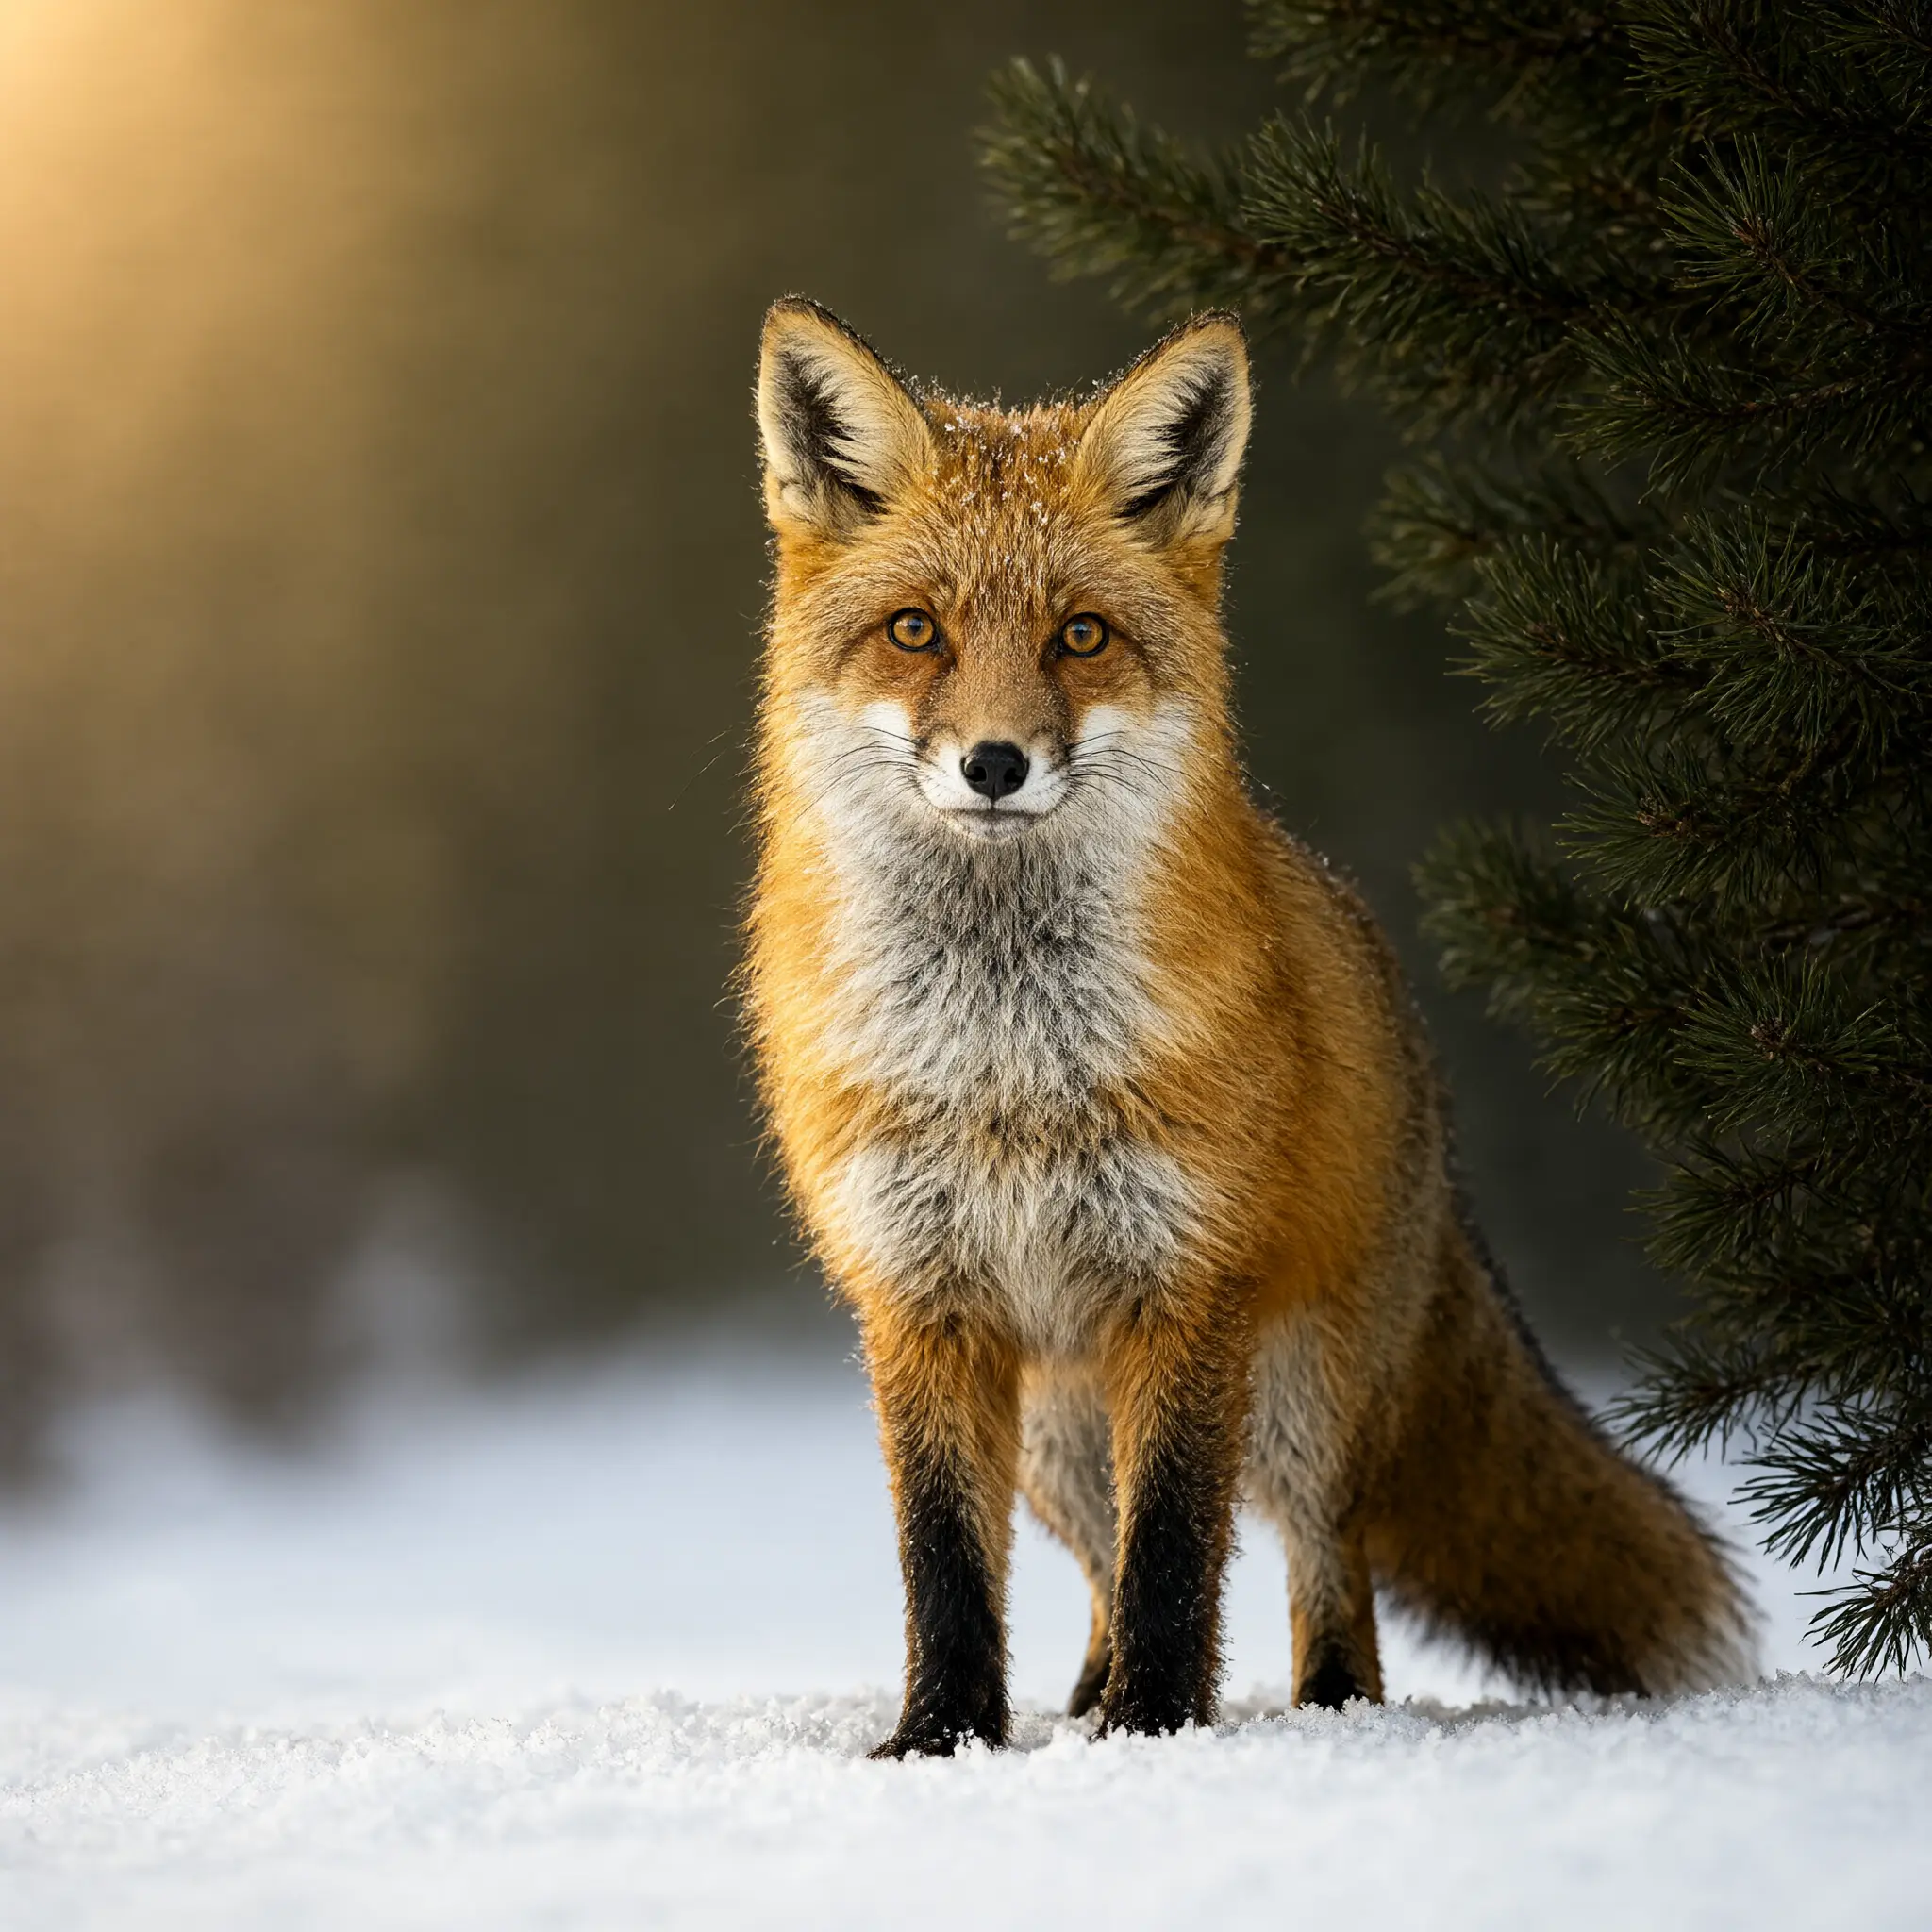
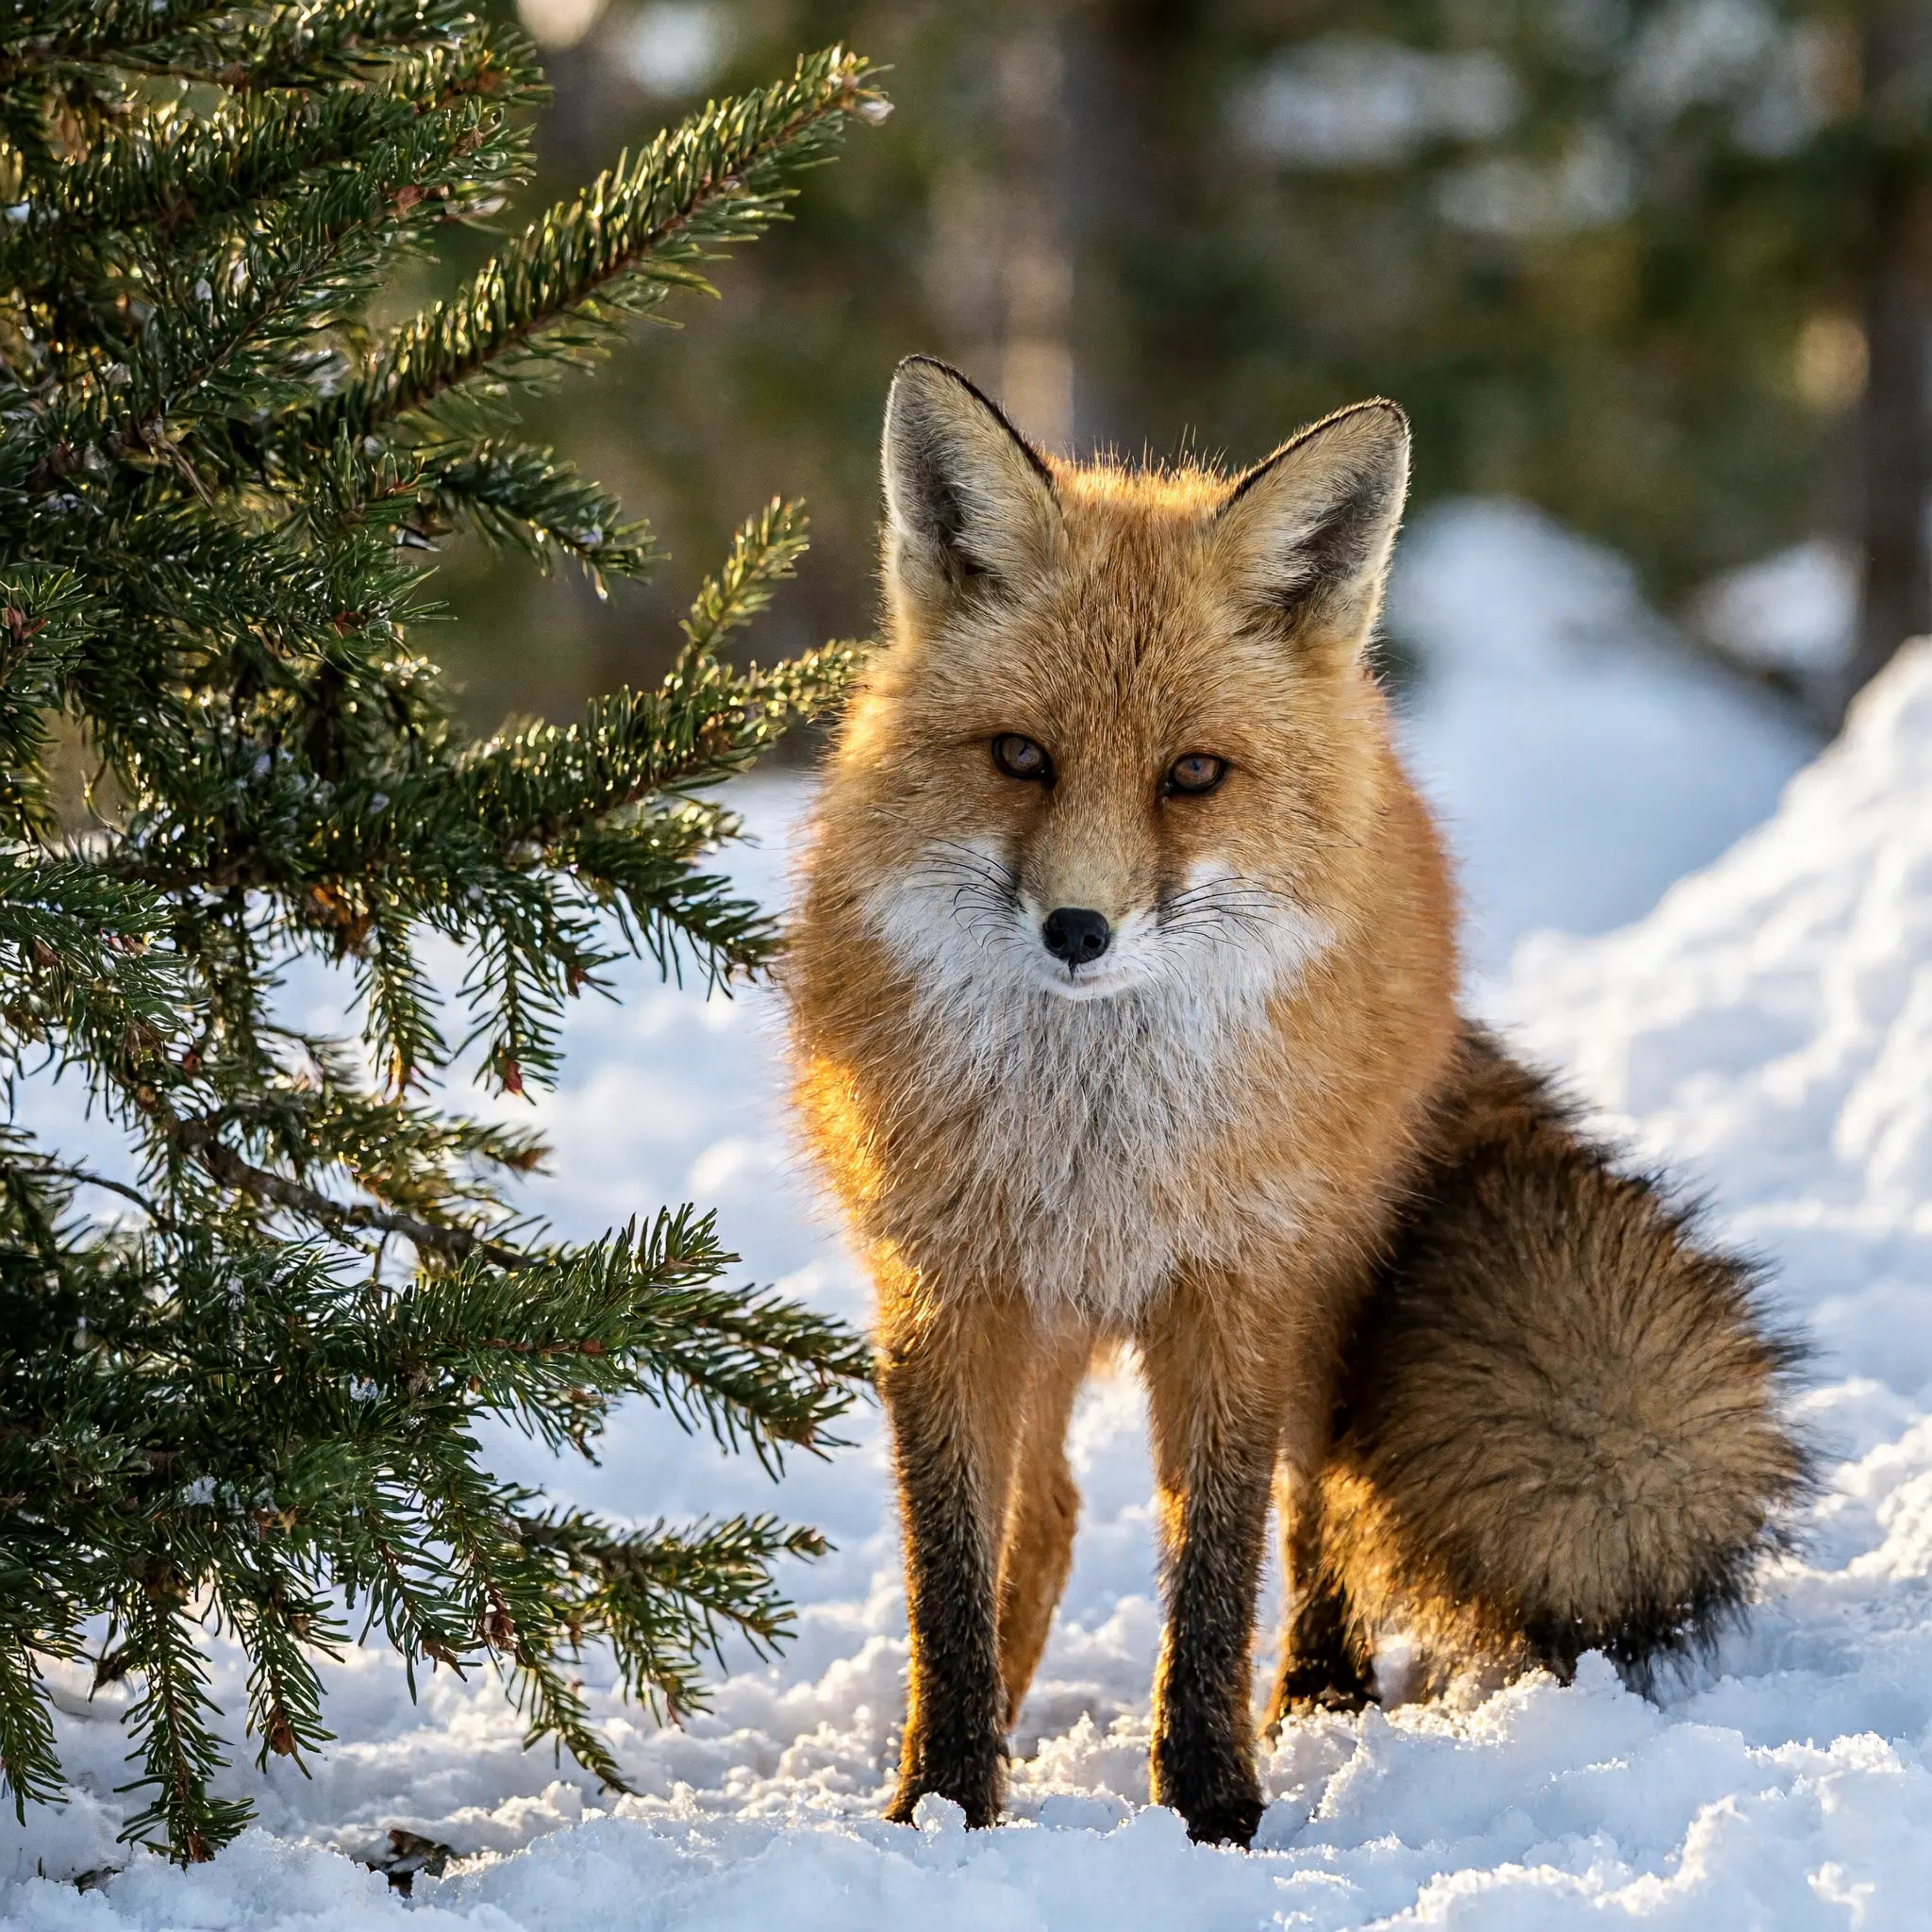
Qwen-Image 2.1 Turbo INT8 · Text to image, 2048×2048Prompt: “A detailed editorial photograph of a small red fox standing in fresh white snow beside a dark green pine tree…”
FLUX 3 Image Klein INT8
Model / precision
Task
Output
Steps
Time
FLUX 3 Image Klein INT8Text to image · 1024×1024
Text to image
1024×1024
16
5.07 s
FLUX 3 Image Klein INT8Text to image · 2048×2048
Text to image
2048×2048
16
24.38 s
MiniMax H3 Image Q3_K
Model / precision
Task
Output
Steps
Time
MiniMax H3 Image Q3_KText to image · 1024×1024
Text to image
1024×1024
6
7.1 s
MiniMax H3 Image Q3_KText to image · 1536×1024
Text to image
1536×1024
6
12.0 s
MiniMax H3 Image Q3_KText to image · 4096×4096
Text to image
4096×4096
6
62.7 s
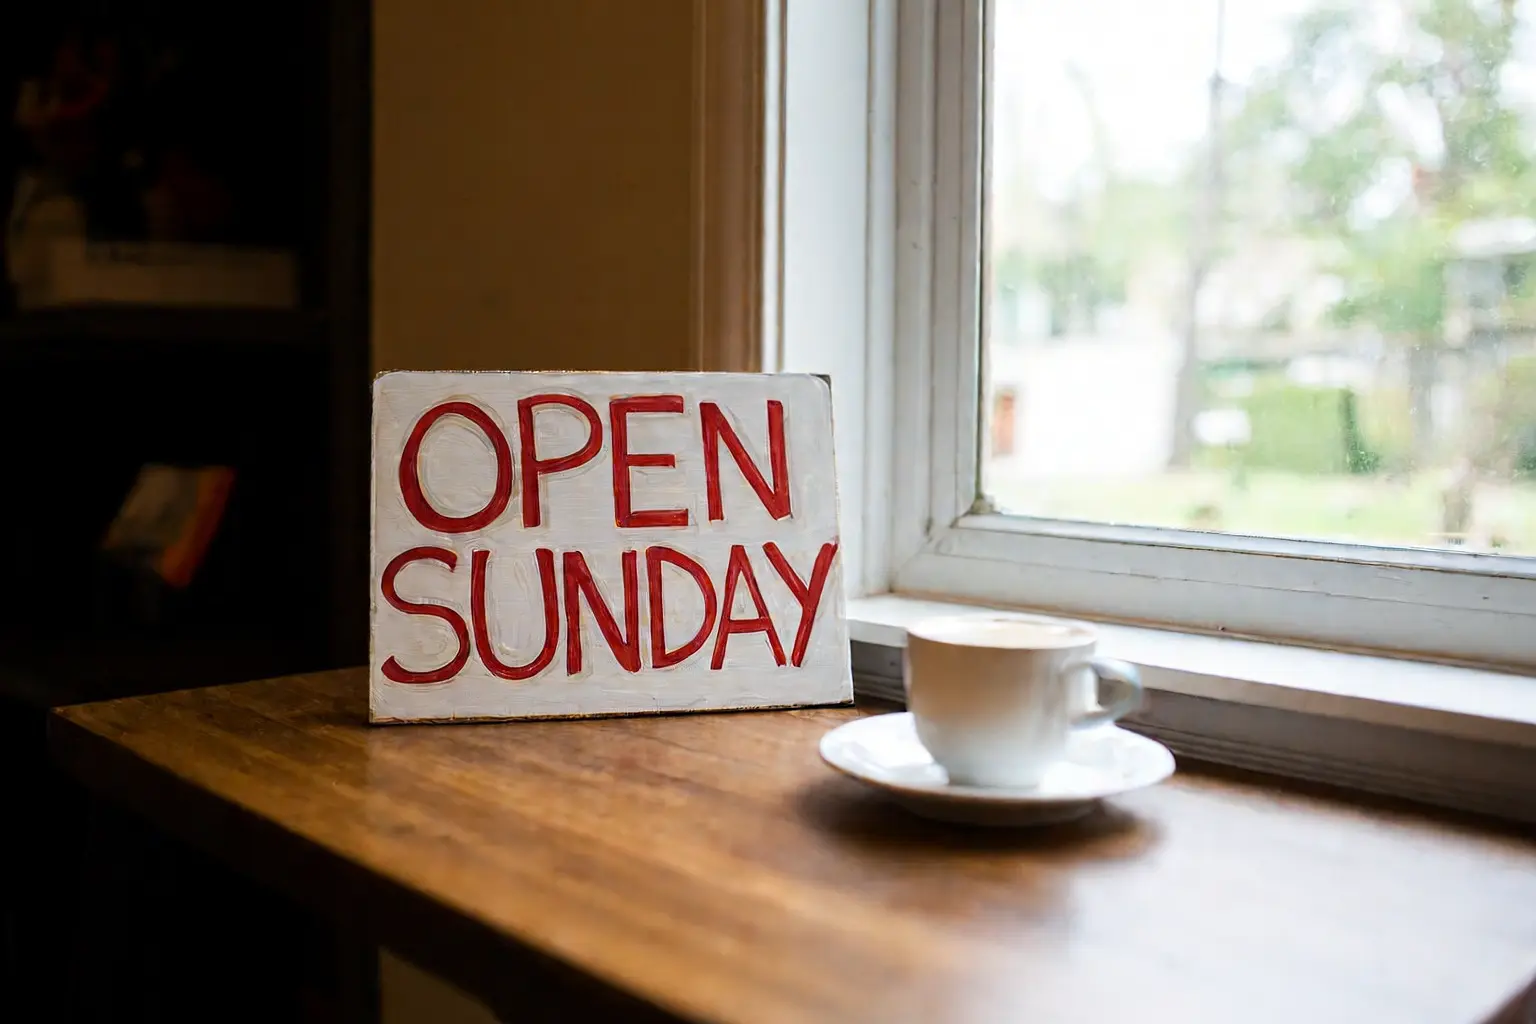
MiniMax H3 Image Q3_K · Text to image, 2048×2048Prompt: “A detailed editorial photograph of a small red fox standing in fresh white snow beside a dark green pine tree. The fox faces the camera, with two alert triangular ears, amber eyes, a black nose and a fluffy orange tail curled to its right. Warm sunrise light enters from the left, illuminating individual hairs and tiny snow crystals. A softly blurred forest fills the background. Natural colors, realistic anatomy, no text, square composition.”MiniMax H3 Image Q3_K · Text to image, 1536×1024A hand-painted sign reading OPEN SUNDAY beside a cup of coffee; both words are spelled correctly.
Wan 2.2 TI2V 5B FP16
Model / precision
Task
Output
Steps
Time
Wan 2.2 TI2V 5B FP16Video · 512×288, 33 frames
Video
512×288, 33 frames
20
51.56 sincludes loading and text encoding
Wan 2.2 TI2V 5B FP16Video · 1280×720, 33 frames
Video
1280×720, 33 frames
20
67.69 sincludes loading and text encoding
Wan 2.2 TI2V 5B FP16Video · 1920×1080, 33 frames
Video
1920×1080, 33 frames
20
170.82 sincludes loading and text encoding
Wan 2.2 TI2V 5B FP16 · Text to video, 1280×720, 2.1 sPrompt: “A red fox standing in snow slowly turns its head toward the camera and blinks. Gentle snowflakes drift through the air. Static camera, natural sunrise light, realistic smooth motion.” No audio track.Wan 2.2 TI2V 5B FP16 · Text to video, 1920×1080, 2.1 sSame prompt and seed as the 720p clip. No audio track.
LTX 2.3 distilled Q4_0
Model / precision
Task
Output
Steps
Time
LTX 2.3 distilled Q4_0Video with audio · 512×288, 33 frames
Video with audio
512×288, 33 frames
8
84.93 sincludes loading and text encoding
LTX 2.3 distilled Q4_0Video with audio · 1280×720, 33 frames
Video with audio
1280×720, 33 frames
8
53.62 sincludes loading and text encoding
LTX 2.3 distilled Q4_0Video with audio · 1920×1080, 33 frames
Video with audio
1920×1080, 33 frames
8
75.84 sincludes loading and text encoding
LTX 2.3 distilled Q4_0 · Text to video with audio, 1280×720, 1.4 sSame prompt and seed as the 1080p clip; at 720p it came out in a cartoon style: “A red fox standing in snow slowly turns its head toward the camera and blinks. Gentle snowflakes drift through the air. Static camera, natural sunrise light, realistic smooth motion. Quiet winter ambience.” Press play with sound on to hear the audio track.LTX 2.3 distilled Q4_0 · Text to video with audio, 1920×1080, 1.4 sPrompt: “A red fox standing in snow slowly turns its head toward the camera and blinks. Gentle snowflakes drift through the air. Static camera, natural sunrise light, realistic smooth motion. Quiet winter ambience.” Press play with sound on to hear the audio track.